
Evaluators
An evaluator is one reusable, versioned scorer — editing one creates a new version, so past runs keep meaning what they meant. Five kinds exist:LLM judge (llm_judge)
LLM judge (llm_judge)
A model grades the response against a rubric you write in plain language. The rubric is compiled into a checklist of atomic, weighted questions; items can be gates that force a fail regardless of the rest of the score. Judges return reasoning and per-item sub-scores. The managed Correctness, Faithfulness, and Hallucination judges use a proportional mode instead: they enumerate the output’s claims and score the share that holds. Judge responses are cached content-addressed, so re-scoring identical inputs is free.
Deterministic (deterministic)
Deterministic (deterministic)
A fixed rule, no model involved. Available checks:
exact_match, contains, regex, json_schema_valid, schema_field_conformance, field_present, reference_field_compare, canonical_fields, tool_selection (precision/recall/F1 over called tools), tool_args_match, goal_state_match, card_constraints, latency, cost, and turn_count. Fast, free, unambiguous — use these wherever the question has a mechanical answer.Trajectory (trajectory)
Trajectory (trajectory)
Judges the path the agent took, not just the output. Two modes: match compares the tool-call sequence against a reference with
strict, unordered, subset, superset, or subsequence semantics (with per-tool argument-match overrides), or judge hands the trajectory to an LLM.Agentic (agentic)
Agentic (agentic)
An LLM judge built for long, multi-step agent runs where there is a lot of trajectory to read and summarise before scoring; on live traces the summarising cascade keeps the judge under its context budget.
Statistical (statistical)
Statistical (statistical)
Scores a whole dataset at once rather than one example at a time:
accuracy, precision, recall, f1 (macro/micro/weighted), calibration (expected calibration error with a bootstrap interval), exact_match, bleu, rouge_l, embedding_cosine, chrf, and duplicate_rate, with configurable prediction normalisation (strip, first_word, last_word, first_line, last_line, or a custom regex: extractor). When the references are labels, the run also reports per-class precision, recall, F1 and a confusion matrix.final_output, turn, step, trajectory, sample, or dataset), a score type (numeric, categorical, or boolean) with a pass threshold, an evidence requirement (the model output, a harness artifact, the trajectory, or a reference answer), and a surface — model, harness, or any — that says which eval-set roles it may serve: a model grader never runs on live trace scoring, a harness grader never runs in generate mode. If a run can’t supply the required evidence, the evaluator abstains or is marked not-applicable instead of producing a meaningless number.
Claims
Every evaluator also carries a claim: what it asserts and at which grain. The claim is what trace scoring uses to compose one execution score out of many verdicts.
The grain is the slice a claim is judged on:
unit (one turn or step), trajectory (the path through the task), terminal (the deliverable), or session (the whole conversation). Grains land in three weighted phases — steps, trajectory, output — and no single evaluator vetoes the composite.
Task bindings
An evaluator can be bound to one of the capability’s tasks with a role: an outcome evaluator judges the task’s deliverable, a step evaluator judges one anchor segment of its route. The Eval library groups evaluators by task, shows each task’s coverage (outcome plus every step), and lists the rest under Unassigned.GET /api/behaviours/coverage/?capability={id} returns the same rollup.
Judges are authored task-scoped from the task’s group in the Eval library or through the upsert_evaluator MCP tool: POST /api/evaluators/author/ takes behaviour, behaviour_role (outcome or step), and — for a step judge — the anchor_segment, validated against the task’s contract. GET /api/behaviours/{id}/authoring-context/ grounds the authoring with the task’s latest contract: anchor sequence, steps, tool set, and terminal. A judge with the trace_scoring role must be bound to a task, and eval_set plus eval_set_role attach the new judge to an eval set in the same call.
Authoring
Author from the Eval library by hand, or describe what you want to test and let Overmind generate the evaluator. The generated prompt template references the agent’s output as{{output.<path>}} and dataset fields as {{reference.<path>}}, and everything stays editable before saving.
A local overmind sync also preloads a starter set per capability in two tiers: rule-based checks compiled from the capability’s card (its output contract, fields, and constraints — no model call), then AI-authored judges grounded in the card, the prompt, and the task map. Authoring reads the capability’s evidence profile — what its telemetry actually carries (declared tasks, explicit units, real tool spans, provenance tags, a declared deliverable) — and refuses a spec whose evidence the traces cannot supply.
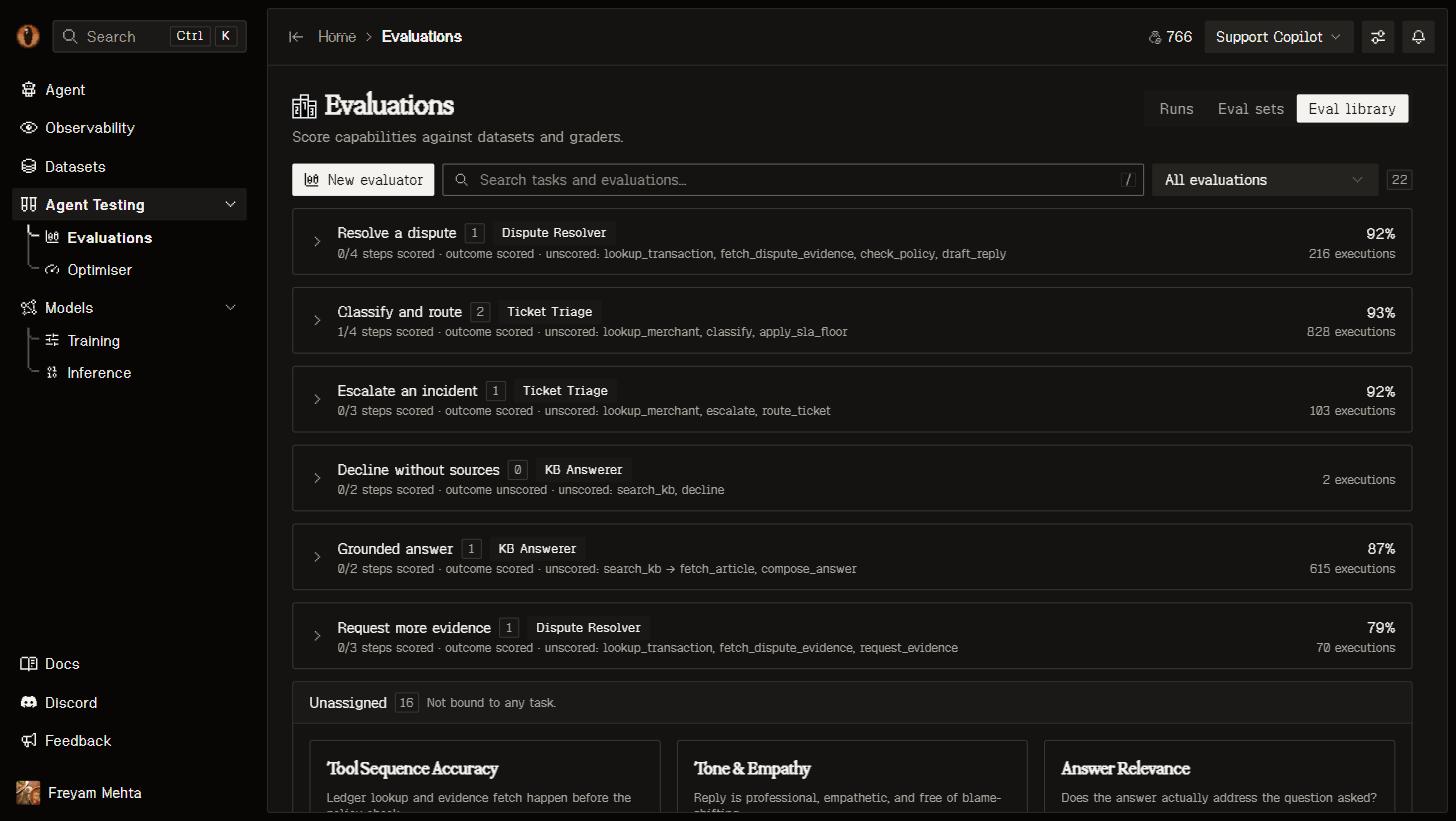
The Eval library grouped by task, with each task's outcome and step coverage.
Eval sets
An eval set is a named group of a capability’s evaluators — the working definition of “good” for that capability. Each member carries a role:- Generative members score outputs produced during eval runs and experiments.
- Trace scoring members run on every production trace, per task execution, writing verdicts and the execution score into Observability. The mechanics are on Trace scoring.
Eval runs
An eval run is a controlled experiment: one data source × N variants × M evaluators.- Data source — a dataset (the exact version is used and frozen, so the run stays reproducible as the dataset evolves) or a trace filter drawing directly from captured traffic.
max_itemscaps how many rows are drawn. - Variants — the columns of the experiment. A variant either generates fresh outputs by re-running a model over each row, or grades existing traces as-is. Each pins a model (a catalogue model, a registered endpoint, or one of your trained models) and optionally a prompt; one variant is the baseline that every other is measured against.
- Evaluators — attached as frozen snapshots at creation, so later library edits can’t change what a completed run measured.
run_evaluation MCP tool, not from a dataset by hand.
params.generation_strategy to per_assistant_turn. The model produces one decision for each recorded assistant turn, using the conversation recorded before that turn as context. Tool calls are evaluated as decisions without executing their tools. Each subsequent turn uses the recorded history, keeping its context independent of the candidate’s previous decisions. Such a run attaches a per-turn judge automatically, and params.replay_dimensions names what it grades. This also applies to conversations containing a single recorded assistant turn; a tool-only decision does not require a final answer.
Generation activity keeps the run’s activity timestamp current. A sample that exceeds the generation worker’s time limit records an error and is excluded from scoring. Scoring starts after sample preparation finishes, so a run can be generating while its score count is still zero.
Reading the report
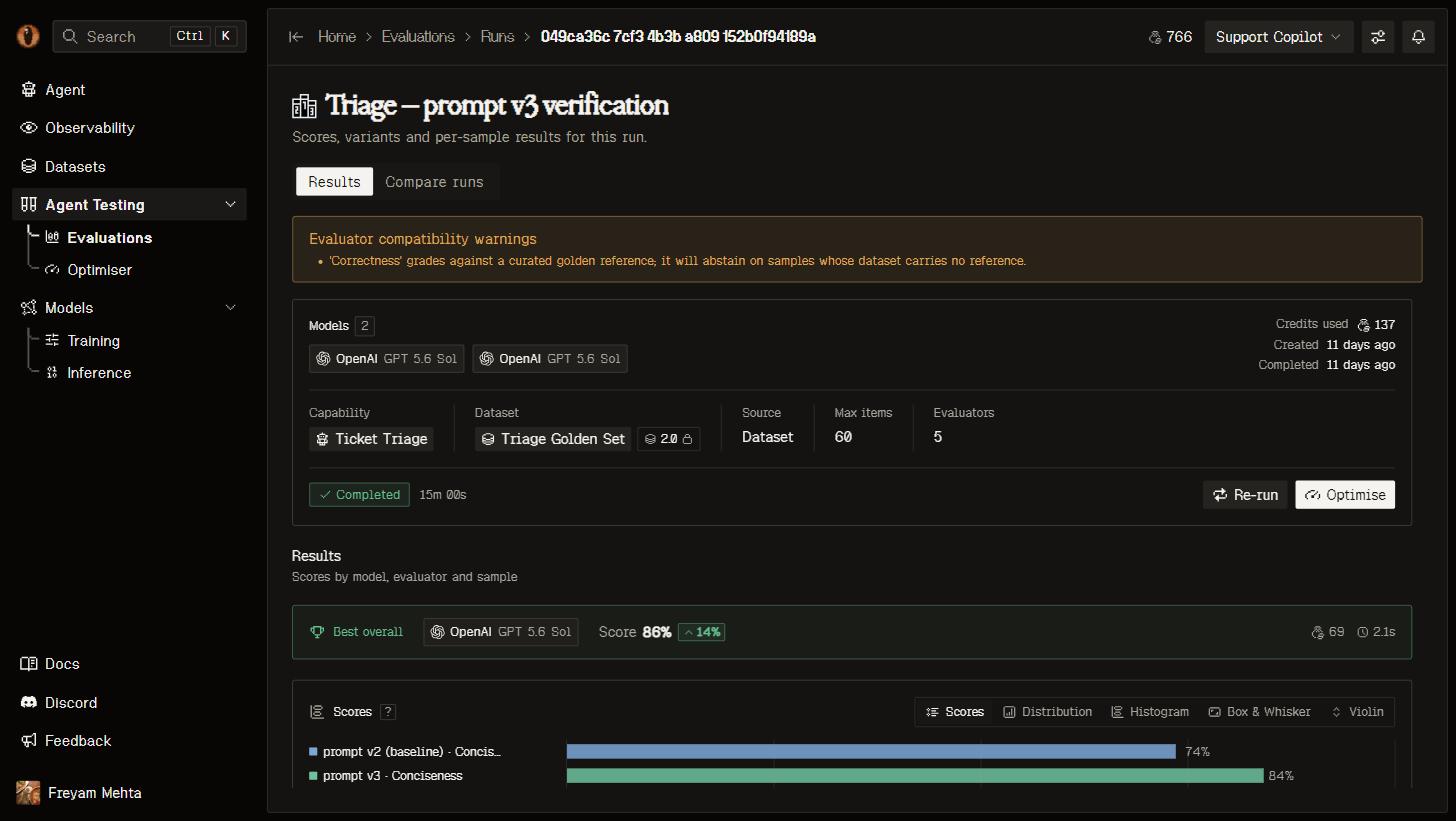
A finished run: per-evaluator pass rates and mean scores per variant, the score distributions, and cost and latency per model.
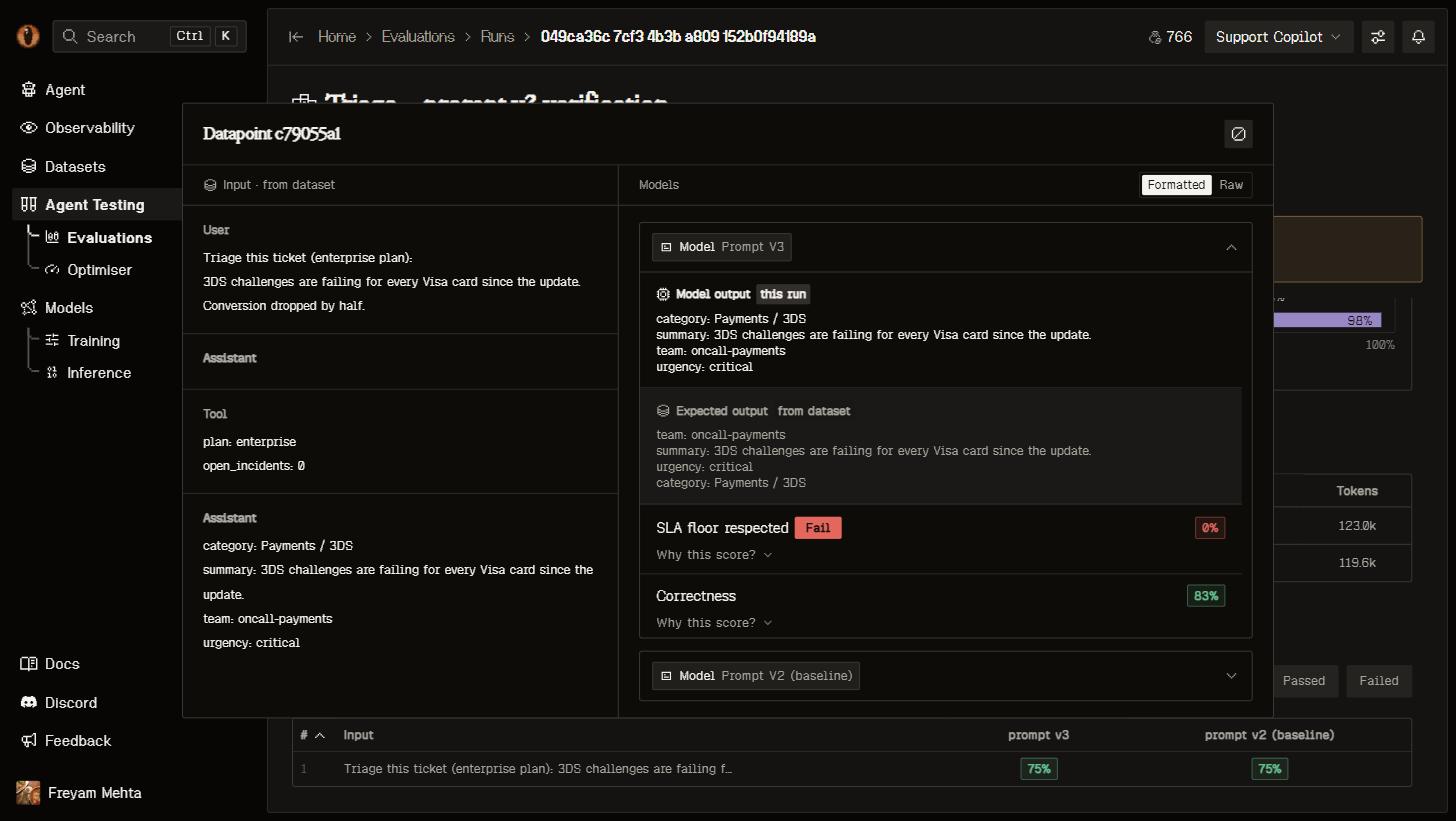
Datapoint drill-down: each evaluator's verdict with reasoning. A check that couldn't be fairly applied is not-applicable and doesn't drag the averages.
- Outcomes are typed. Every score is
scored,abstained,not_applicable,skipped, orerror— and onlyscoredresults feed averages and pass rates. - Samples can be degraded. Each trace is normalised into a canonical transcript before scoring; if it can’t be faithfully reconstructed, the sample is marked degraded and excluded from aggregates rather than silently polluting them. Failure scores also carry a role — root cause vs. propagated — so one upstream failure doesn’t read as five independent ones.
Calibrating judges
Samples accept annotations — human labels with an optional note, written through theannotate_evaluation_sample MCP tool — giving you ground truth to compare judge behaviour against. When a judge and your annotations disagree consistently, tighten the rubric; the checklist compilation makes it easy to see which specific criterion is drifting.
Getting started sensibly
Begin with three to five metrics: a deterministic check or two for your output contract (json_schema_valid, tool_selection), one judged metric for the quality dimension you care about, and a reference-based check if you have labelled data. Run them against a small real dataset, read the per-example reasoning, fix the rubric where the judge misunderstood you — then scale up.