
Prerequisites
1
A capability from your code
Candidates are edits to source, so the capability must be one
overmind scan push created from an entry declared in overmind.toml; the CLI resolves -c <slug> through that file, and the run records the capability’s entrypoint_fn as the entrypoint under test. See Agent & Capabilities.2
An eval dataset
The run replays the agent over the rows of an eval dataset in the same project whose active version fits the eval contract; the inputs must be a shape the agent can be invoked with. The dataset’s contracts are the only creation gate — a wrong entrypoint signature surfaces at the smoke test. See Datasets.
3
An eval set
Candidates are graded by the eval set you pick, or the capability’s active eval set by default. The set must belong to the capability. See Eval.
4
A coding agent in the repository
Your agent executes in your environment, not Overmind’s. The loop is driven from your checkout by the
overmind CLI, and the candidate diffs are written by your coding agent. Optimiser → New run in the Console hands you the prompt to paste — Harness for prompt and code optimisation, Backtesting for model comparison — which the /overmind optimise and /overmind backtest commands run end to end.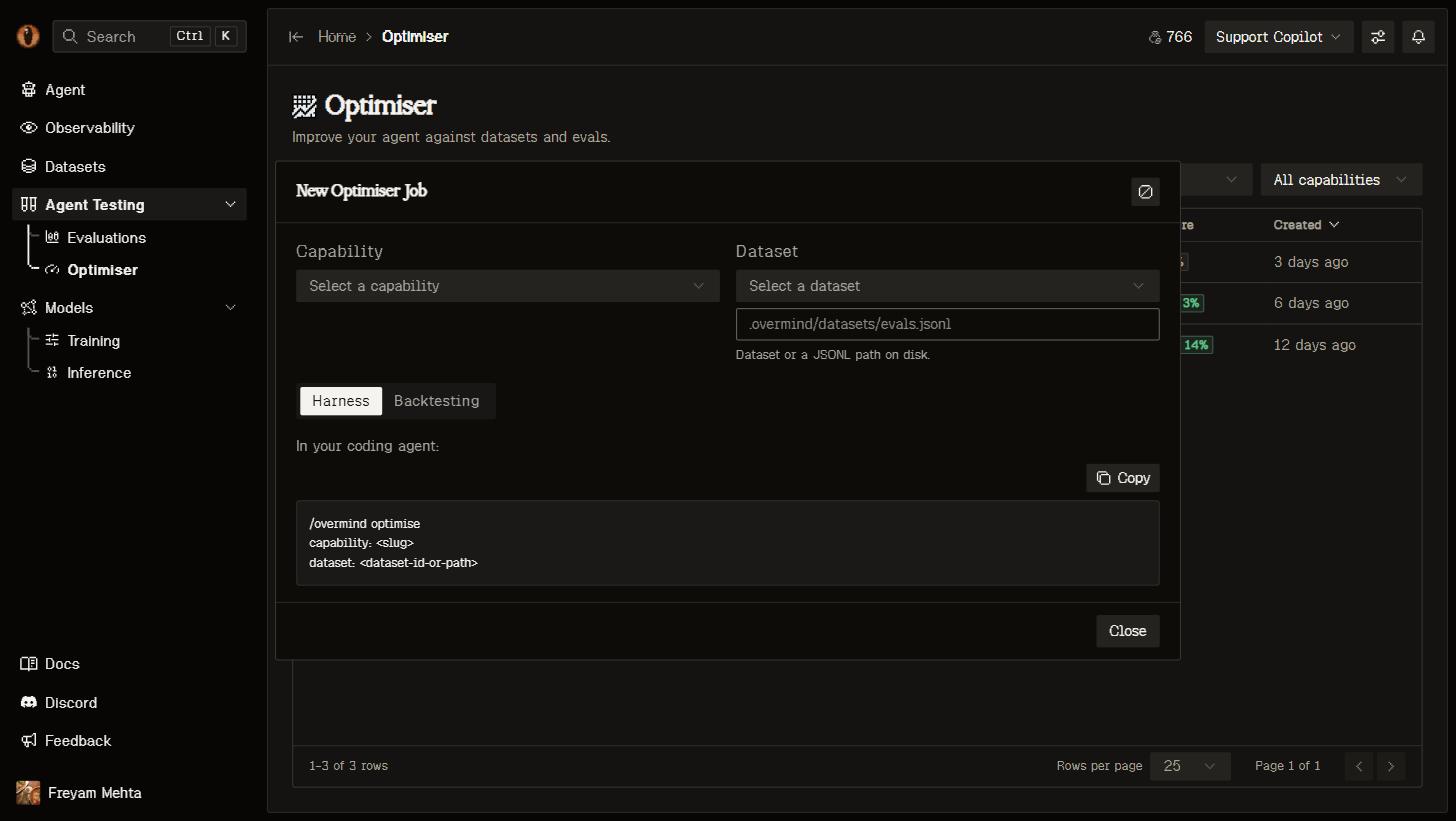
New run: the Harness and Backtesting prompts the coding agent runs.
How a run works
The client owns codegen, the smoke test, and every datapoint run; the server holds the dataset version, scores posted outputs, and records the winner. Each step is one CLI verb, andovermind optimise next tells the coding agent which one comes next:
-e <experiment-id>; without it the CLI uses the run recorded in .overmind/optimise_state.json. start pulls the run’s dataset version once to .overmind/datasets/<cell-id>.jsonl and never re-fetches it. See the CLI.
The command template is one shell command that runs the capability on a single datapoint and prints its output, with placeholders __DATAPOINT_INPUT__, __EXPERIMENT_ID__, __CAPABILITY_ID__, __CANDIDATE_ID__, __ITERATION_ID__, __DATAPOINT_INDEX__ and __PROJECT_ID__. A run opens with a smoke test — before spending anything, the first datapoint runs through the template to verify the entrypoint can be invoked. Then it measures the baseline: your agent exactly as it is, scored across the whole dataset as iteration 0.
Each subsequent iteration takes the batch of candidate diffs from the coding agent, applies each in its own git worktree under .overmind/worktrees/, replays every datapoint through it — one shared pool of eight workers across all candidates and datapoints — posts the outputs, and waits for the platform to score them with the same eval pipeline used everywhere else: every candidate links to a full eval run you can open. A candidate becomes the new best only if it beats the best score so far. next returns COMPLETE when the iteration budget is spent or after patience consecutive iterations without improvement; complete removes the worktrees and closes the run. A run can be cancelled at any point.
Modes
A backtest runs the repository with its provider calls redirected to OpenRouter:
overmind.backtest.rewrite_repo(".") rewrites OpenAI, AsyncOpenAI, Anthropic, AsyncAnthropic and ChatOpenAI constructors to read OPENROUTER_MODEL, OPENROUTER_API_KEY and the OpenRouter base URL from the environment, and reports leftover call sites (ChatAnthropic, Google GenAI, Vertex) for the coding agent to patch. For each candidate the loop then runs the datapoints with OPENROUTER_MODEL set to that candidate’s model and OPENROUTER_API_KEY from your environment (OPENAI_API_KEY as a fallback).
A backtest ranks its candidates coverage-fair: by score, then by the share of datapoints that produced gradeable output, then by fewest excluded datapoints (failed runs and empty outputs) — so a model that scored well by failing hard datapoints does not win. The incumbent keeps the overall win on a tie. When every candidate ties and the eval suite left card claims uncovered, no model is selected and the run says so.
Following a run
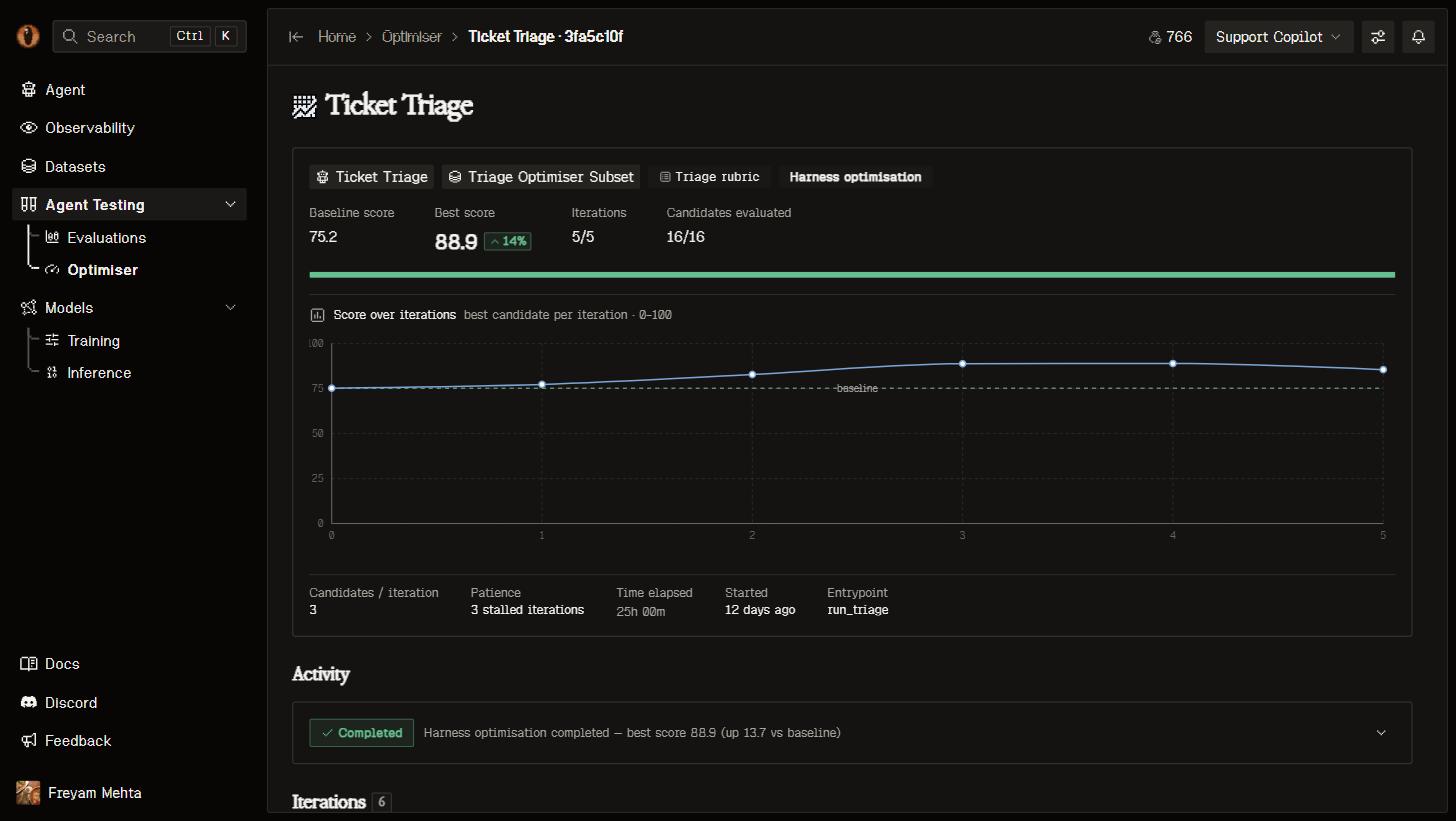
A finished run: baseline to best over five iterations, with the score-per-iteration chart and the iteration log.
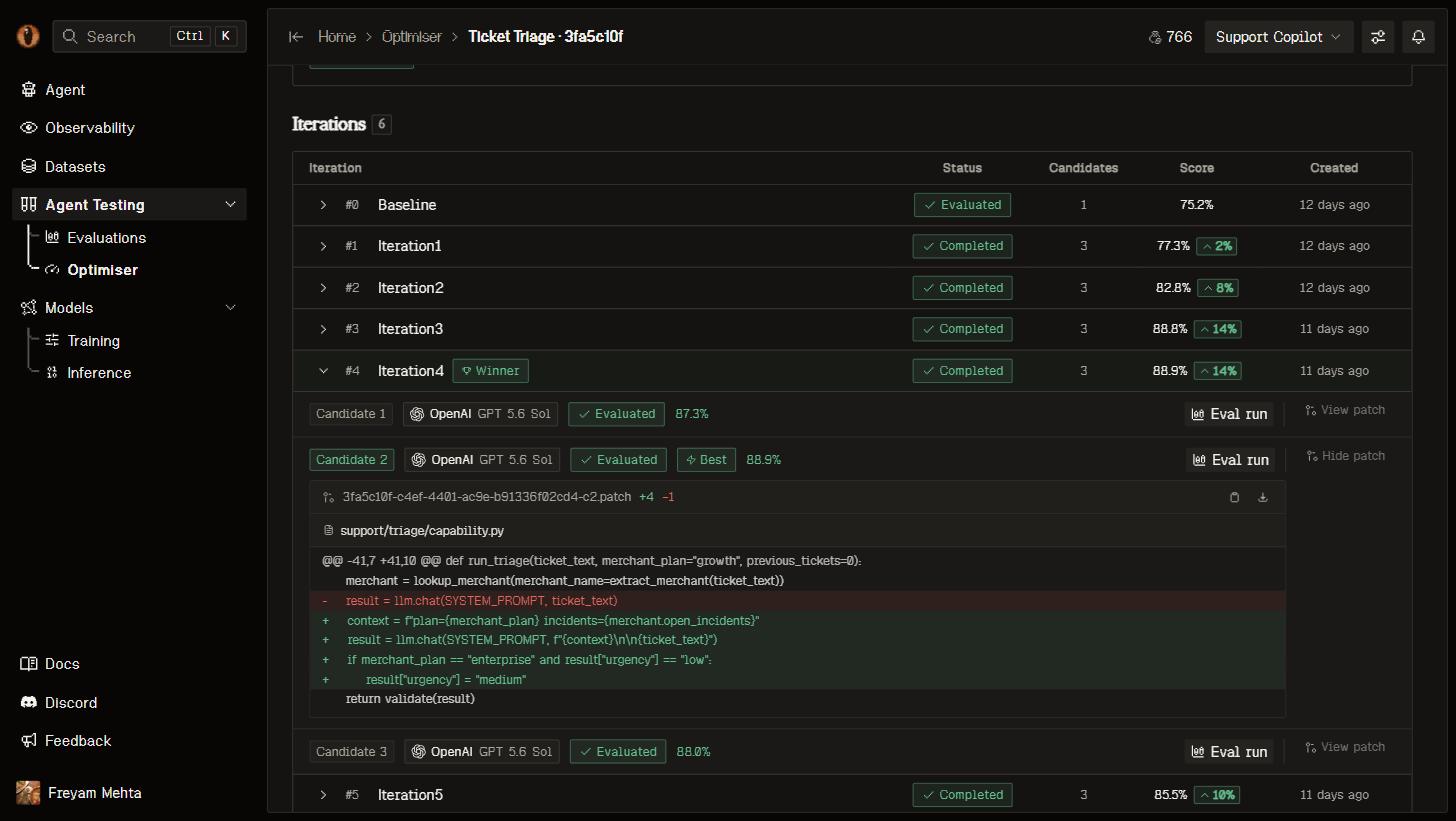
An expanded iteration: the winning candidate's patch is a reviewable diff, and every candidate links to the eval run that scored it.
scheduled → baseline → evaluating_baseline_outputs → iterating → evaluating_candidate_outputs → … → completed, or failed, cancelled, paused.
The result is a scored diff
The winning candidate keeps its diff on the record: the patch on the run page. Apply it in your repository with your normal git workflow; the coding agent that drove the loop already has it applied in the candidate’s worktree untilcomplete removes them. Because candidates were scored with the same evaluators you use everywhere else, the headline score is directly comparable to your eval runs and live trace scores. A backtest’s result is the winning model id, which you pin in your configuration yourself.
API
POST .../template/, .../add-iteration/, .../results/, .../evaluate/, .../complete/ — are what the CLI posts; you do not call them by hand. POST /api/optimizer-experiments/ creates a run with capability, dataset, optional cell and eval_set, mode, model_ids, the budget fields and openrouter_key_source (platform or local). Over MCP, check_optimizer_readiness validates the dataset, eval set, model ids, credits and plan quota, start_optimizer schedules a run in any mode and returns the CLI command to drive it, and inspect_optimizer_result reads iterations, candidate patches, the winner, and the next action.
Good to know
- You measure what you optimise. If your evaluators don’t capture what you care about, the Optimiser will faithfully improve the wrong thing. Invest in Eval first.
- Model costs are yours. The loop runs your agent for real — iterations × candidates × datapoints model calls under your provider keys. The budget is the cost lever; the judge calls that score outputs are metered on the platform.
- The dataset defines the situations explored. A narrow dataset produces improvements narrow to match; refresh it with recent traces periodically.
- Plateaus point at the model. When several runs on a capability stop improving, the run page suggests Models — by then you already have the dataset and eval set it needs.