> ## Documentation Index
> Fetch the complete documentation index at: https://docs.overmindlab.ai/llms.txt
> Use this file to discover all available pages before exploring further.

# Models

> Train a model you own on your own traffic, and see it measured against the model you run today.

export const ModelCatalog = () => {
  const labels = {
    cisco: "Cisco",
    google: "Google",
    liquid: "Liquid",
    meta: "Meta",
    nvidia: "NVIDIA",
    openai: "OpenAI",
    qwen: "Qwen"
  };
  const tiers = ["compact", "small", "mid", "large"];
  const rows = [["qwen", "Qwen 3.5 4B", "Qwen/Qwen3.5-4B", "yes", "compact", "262144 inference, 131072 train, tool calling"], ["qwen", "Qwen 3.5 2B", "Qwen/Qwen3.5-2B", "yes", "compact", "262144 inference, 131072 train, tool calling"], ["qwen", "Qwen 3.5 0.8B", "Qwen/Qwen3.5-0.8B", "yes", "compact", "262144 inference, 131072 train, tool calling"], ["qwen", "Qwen 3 4B", "Qwen/Qwen3-4B", "yes", "compact", "131072 inference, 40960 train, tool calling"], ["qwen", "Qwen 3 1.7B", "Qwen/Qwen3-1.7B", "yes", "compact", "131072 inference, 40960 train, no tool calling"], ["qwen", "Qwen 3 0.6B", "Qwen/Qwen3-0.6B", "yes", "compact", "131072 inference, 40960 train, no tool calling"], ["qwen", "Qwen 2.5 0.5B Instruct", "Qwen/Qwen2.5-0.5B-Instruct", "yes", "compact", "32768 context, no tool calling"], ["meta", "Llama 3.2 3B Instruct", "meta-llama/Llama-3.2-3B-Instruct", "yes", "compact", "131072 context, no tool calling"], ["meta", "Llama 3.2 1B Instruct", "meta-llama/Llama-3.2-1B-Instruct", "yes", "compact", "131072 context, no tool calling"], ["liquid", "LFM2.5 1.2B Instruct", "LiquidAI/LFM2.5-1.2B-Instruct", "yes", "compact", "32768 context, tool calling"], ["liquid", "LFM2.5 350M", "LiquidAI/LFM2.5-350M", "yes", "compact", "32768 context, tool calling"], ["liquid", "LFM2.5 230M", "LiquidAI/LFM2.5-230M", "yes", "compact", "32768 context, tool calling"], ["cisco", "Antares 1B (Security)", "fdtn-ai/antares-1b", "yes", "compact", "131072 context, tool calling"], ["cisco", "Antares 350M (Security)", "fdtn-ai/antares-350m", "yes", "compact", "32768 context, tool calling"], ["qwen", "Qwen 3.5 9B", "Qwen/Qwen3.5-9B", "yes", "small", "262144 inference, 131072 train, tool calling"], ["qwen", "Qwen 3 8B", "Qwen/Qwen3-8B", "yes", "small", "131072 inference, 40960 train, tool calling"], ["qwen", "Qwen 2.5 7B Instruct", "Qwen/Qwen2.5-7B-Instruct", "yes", "small", "131072 inference, 32768 train, tool calling"], ["google", "Gemma 4 E4B", "google/gemma-4-E4B-it", "yes", "small", "131072 context, tool calling"], ["google", "Gemma 4 E2B", "google/gemma-4-E2B-it", "yes", "small", "131072 context, tool calling"], ["meta", "Llama 3.1 8B Instruct", "meta-llama/Llama-3.1-8B-Instruct", "yes", "small", "131072 context, tool calling"], ["qwen", "Qwen 3.8 27B", "Qwen/Qwen3.8-27B", "LoRA-only", "mid", "262144 context, tool calling"], ["qwen", "Qwen 3.6 27B", "Qwen/Qwen3.6-27B", "LoRA-only", "mid", "262144 context, tool calling"], ["qwen", "Qwen 3.5 27B", "Qwen/Qwen3.5-27B", "LoRA-only", "mid", "262144 context, tool calling"], ["qwen", "Qwen 3 Coder 30B MoE", "Qwen/Qwen3-Coder-30B-A3B-Instruct", "LoRA-only", "mid", "262144 inference, 65536 train, tool calling"], ["qwen", "Qwen 3 14B", "Qwen/Qwen3-14B", "yes", "mid", "131072 inference, 40960 train, tool calling"], ["qwen", "Qwen 2.5 14B Instruct", "Qwen/Qwen2.5-14B-Instruct", "yes", "mid", "131072 inference, 32768 train, tool calling"], ["google", "Gemma 4 12B", "google/gemma-4-12B-it", "yes", "mid", "262144 inference, LoRA 131072, full 65536, tool calling"], ["openai", "GPT-OSS 20B", "openai/gpt-oss-20b", "LoRA-only", "mid", "131072 context, tool calling"], ["qwen", "Qwen 3.5 35B MoE", "Qwen/Qwen3.5-35B-A3B", "LoRA-only", "large", "262144 context, tool calling"], ["qwen", "Qwen 3 32B", "Qwen/Qwen3-32B", "LoRA-only", "large", "131072 inference, 40960 train, tool calling"], ["qwen", "Qwen 2.5 72B Instruct", "Qwen/Qwen2.5-72B-Instruct", "LoRA-only", "large", "131072 inference, 32768 train, no tool calling"], ["qwen", "Qwen 2.5 32B Instruct", "Qwen/Qwen2.5-32B-Instruct", "LoRA-only", "large", "131072 inference, 32768 train, tool calling"], ["qwen", "Qwen 2.5 Coder 32B Instruct", "Qwen/Qwen2.5-Coder-32B-Instruct", "LoRA-only", "large", "131072 inference, 32768 train, tool calling"], ["google", "Gemma 4 31B", "google/gemma-4-31B-it", "LoRA-only", "large", "262144 inference, 65536 train, tool calling"], ["google", "Gemma 4 26B-A4B", "google/gemma-4-26B-A4B-it", "LoRA-only", "large", "262144 inference, 65536 train, tool calling"], ["meta", "Llama 3.3 70B Instruct", "meta-llama/Llama-3.3-70B-Instruct", "LoRA-only", "large", "131072 context, tool calling"], ["meta", "Muse Glimmer 30B", "unsloth/Muse-Glimmer-30B", "LoRA-only", "large", "131072 context, tool calling"], ["nvidia", "Nemotron 3.5 Lightning 30B-A3B", "nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B", "LoRA-only", "large", "262144 context, tool calling"]];
  const providers = ["qwen", "meta", "liquid", "cisco", "google", "openai", "nvidia"];
  const [query, setQuery] = useState("");
  const [providerFilter, setProviderFilter] = useState([]);
  const [tierFilter, setTierFilter] = useState([]);
  const toggle = (list, value) => list.includes(value) ? list.filter(item => item !== value) : [...list, value];
  const needle = query.trim().toLowerCase();
  const visible = rows.filter(([provider, name, id, trainable, tier, notes]) => {
    if (providerFilter.length && !providerFilter.includes(provider)) return false;
    if (tierFilter.length && !tierFilter.includes(tier)) return false;
    if (!needle) return true;
    return [labels[provider], name, id, trainable, tier, notes].join(" ").toLowerCase().includes(needle);
  });
  const chipLogo = provider => <span aria-hidden="true" className="om-model-chip-logo" data-logo={provider} />;
  return <div className="om-model-catalog" data-table-wrapper="">
      <div className="om-model-catalog-toolbar">
        <input type="search" className="om-model-catalog-search" value={query} placeholder="Search" aria-label="Search models" onChange={event => setQuery(event.target.value)} onKeyDown={event => {
    if (event.key === "Escape") setQuery("");
  }} />
        <div className="om-model-catalog-filters" role="group" aria-label="Provider">
          {providers.map(provider => {
    const on = providerFilter.includes(provider);
    return <button key={provider} type="button" className="om-model-chip om-filter-chip" aria-pressed={on} onClick={() => setProviderFilter(toggle(providerFilter, provider))}>
                {chipLogo(provider)}
                <span>{labels[provider]}</span>
              </button>;
  })}
        </div>
        <div className="om-model-catalog-filters" role="group" aria-label="Tier">
          {tiers.map(tier => {
    const on = tierFilter.includes(tier);
    return <button key={tier} type="button" className="om-model-chip om-filter-chip" aria-pressed={on} onClick={() => setTierFilter(toggle(tierFilter, tier))}>
                <span>{tier}</span>
              </button>;
  })}
        </div>
      </div>
      <table>
        <thead>
          <tr>
            <th>Name</th>
            <th>Serving id</th>
            <th>Trainable</th>
            <th>Tier</th>
            <th>Notes</th>
          </tr>
        </thead>
        <tbody>
          {visible.length === 0 ? <tr className="om-model-catalog-empty">
              <td colSpan={5}>No models match.</td>
            </tr> : visible.map(([provider, name, id, trainable, tier, notes]) => <tr key={id}>
                <td>
                  <span className="om-model-chip" title={name}>
                    {chipLogo(provider)}
                    <span>{name}</span>
                  </span>
                </td>
                <td>
                  <code>{id}</code>
                </td>
                <td>{trainable}</td>
                <td>{tier}</td>
                <td>{notes}</td>
              </tr>)}
        </tbody>
      </table>
    </div>;
};

Fine-tune an open-weight model on the data your agent has already produced. You pick the model, Overmind runs the training on GPUs, streams the loss curves while it goes, and scores the finished model against the one your capability runs in production — with the same judges you use everywhere else.

The model is yours. Its weights are downloadable, and it serves through an [OpenAI-compatible API](/models/inference#calling-your-model) you call with your existing client.

## What you need

|                   |                                                                                        |
| ----------------- | -------------------------------------------------------------------------------------- |
| **Capability**    | The capability you're training for. Its production model becomes the benchmark to beat |
| **Training data** | A **train** dataset that fits the [train contract](/core/datasets#contracts)           |
| **Eval data**     | An **eval** dataset, used to score both the baseline and your trained model            |
| **Graders**       | An eval set with at least one enabled judge                                            |

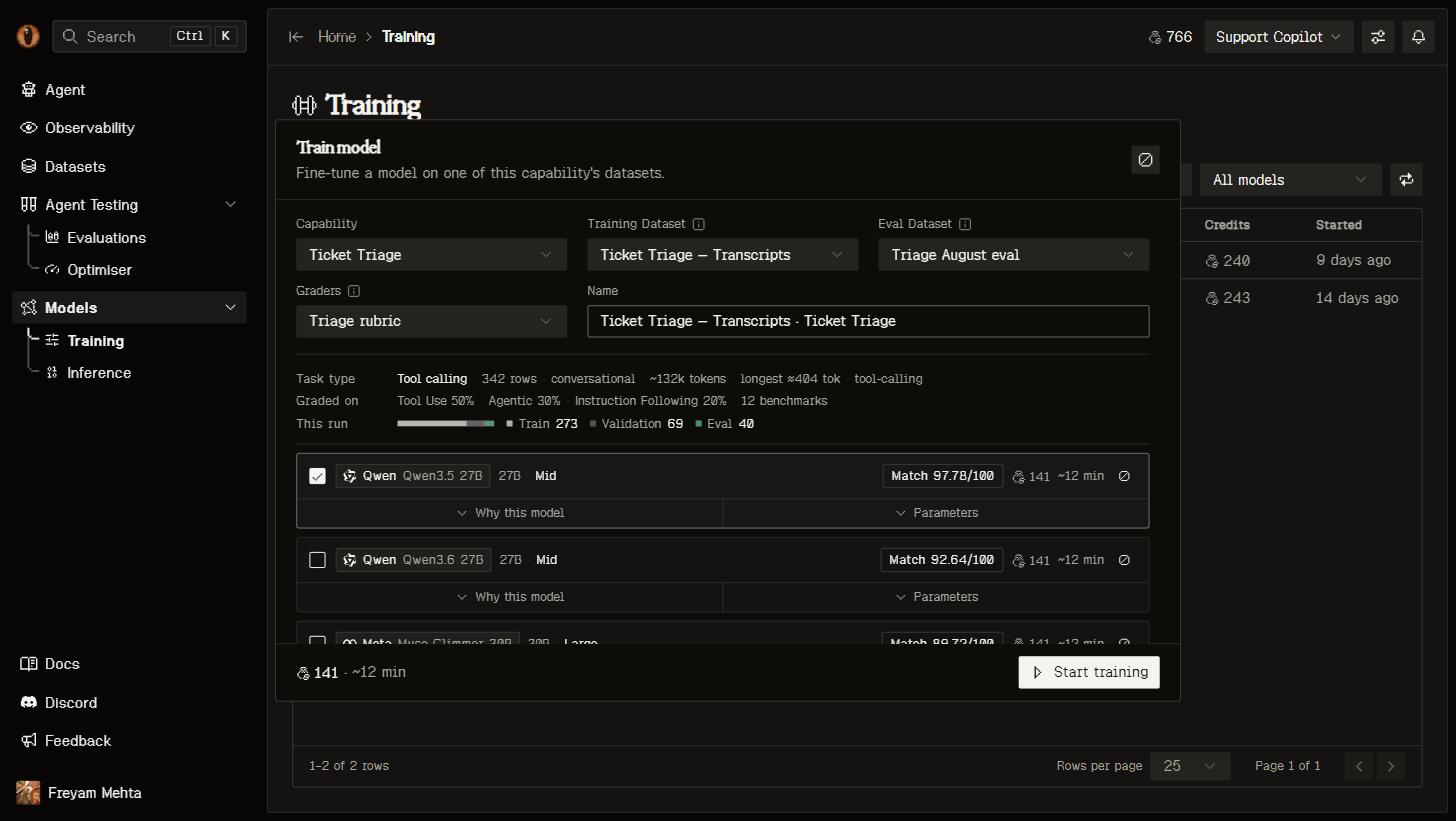
Your train and eval data must not share the same runs. Overmind counts the overlap for you and shows it in the wizard before you launch; anything overlapping is dropped from training rather than quietly inflating your score.

<Frame caption="The training wizard: your data and graders on the left, the recommended models with cost and time estimates on the right.">
  <img src="https://mintcdn.com/overmind-b84ae13c/OG-4bZDDAnV78HJp/images/platform/training-wizard.jpg?fit=max&auto=format&n=OG-4bZDDAnV78HJp&q=85&s=7f8b6e72e42d1e6c738972d94346154b" alt="Training wizard with dataset setup and model picker" width="1456" height="821" data-path="images/platform/training-wizard.jpg" />
</Frame>

## Pick a model

The wizard ranks the catalogue for your data and estimates cost and duration for each option before you spend anything.
<ModelCatalog />

Three things can rule a model out, and the wizard handles all three for you:

* **Context.** A model's training context is often shorter than its inference window. One that can't fit your longest row is dropped from the recommendations.
* **Tool calling.** If your data contains tool calls, only models that support them are offered.
* **Adapters.** Larger dense models and every mixture-of-experts model train as LoRA adapters; the picker says so instead of offering a choice.

## Launch

One run can launch several experiments at once, so you can try two learning rates or two base models side by side and compare them on the same page. Each experiment has its own **Epochs**, **Learning rate** and **Batch**, plus **Rank**, **Alpha** and **Dropout** when it's training a LoRA adapter. The panel tells you what your data looks like — rows, tokens, longest row, whether it contains tool calls — so the numbers aren't guesswork.

Your coding agent can do the whole thing: `/overmind finetune` checks you're ready, estimates the cost, launches the run, and follows it to the end.

## Watch it train

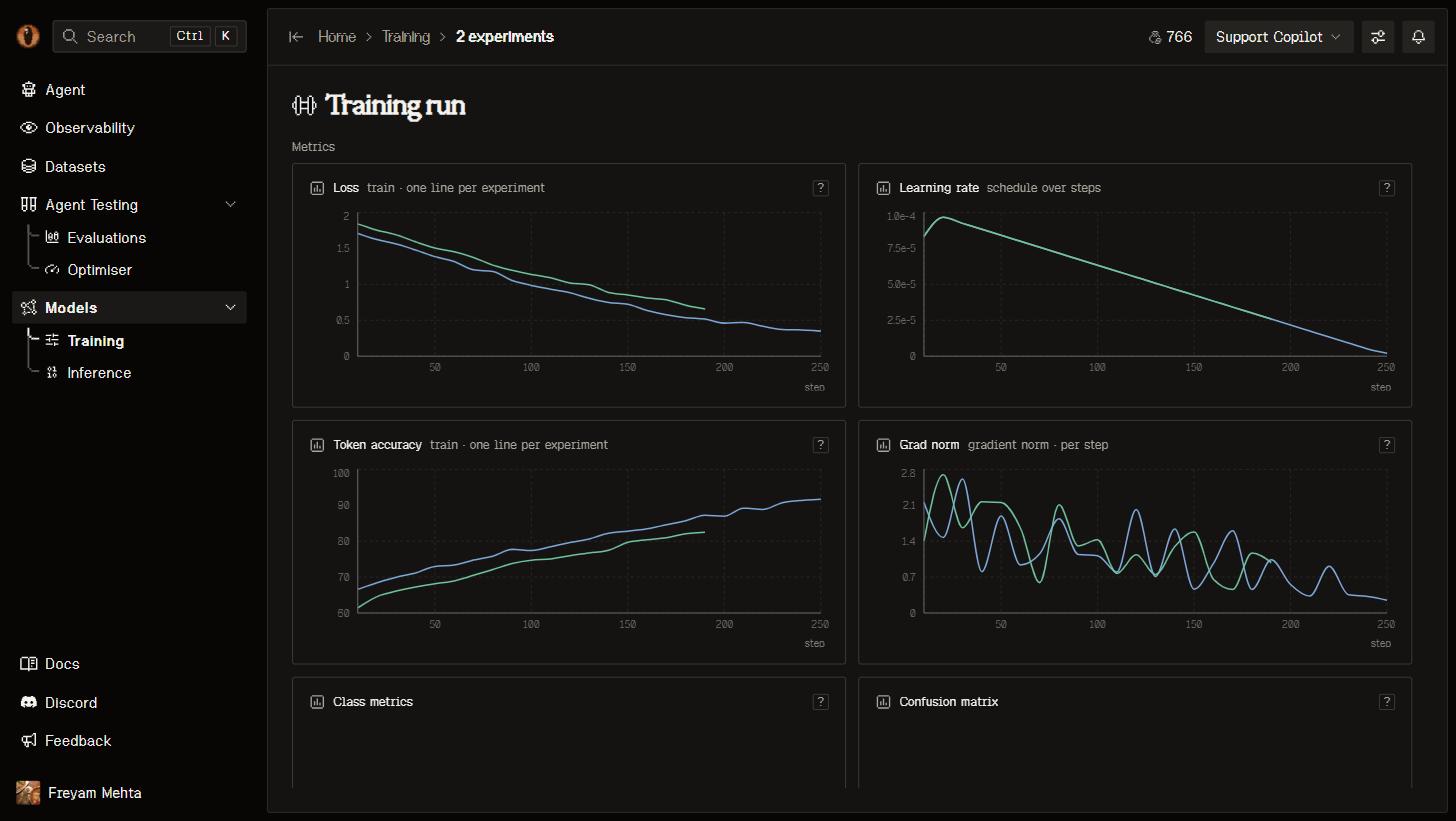
<Frame caption="A finished experiment: train and validation loss per step, the learning-rate schedule, token accuracy and gradient norm.">
  <img src="https://mintcdn.com/overmind-b84ae13c/OG-4bZDDAnV78HJp/images/platform/training-monitor.jpg?fit=max&auto=format&n=OG-4bZDDAnV78HJp&q=85&s=5c2a0384dc0bea76e19e6973600fff54" alt="Training run monitor with loss curves and configuration" width="1456" height="821" data-path="images/platform/training-monitor.jpg" />
</Frame>

A job moves from queued, through training, to deploying, and lands on succeeded. While it runs you get per-step train and validation loss, learning rate, token accuracy and gradient norm, alongside steps completed, an ETA, tokens processed and credits used. You can cancel a run at any point, and retry one that failed.

## The benchmark

This is the part that tells you whether the training was worth it. Every run with eval data and graders scores two things on the same rows with the same judges:

1. **Baseline** — the model your capability runs today, captured when you launched.
2. **Final** — your trained model, once it's serving.

The headline is the delta between them, with each grader's score underneath and a link to the full eval run behind every number.
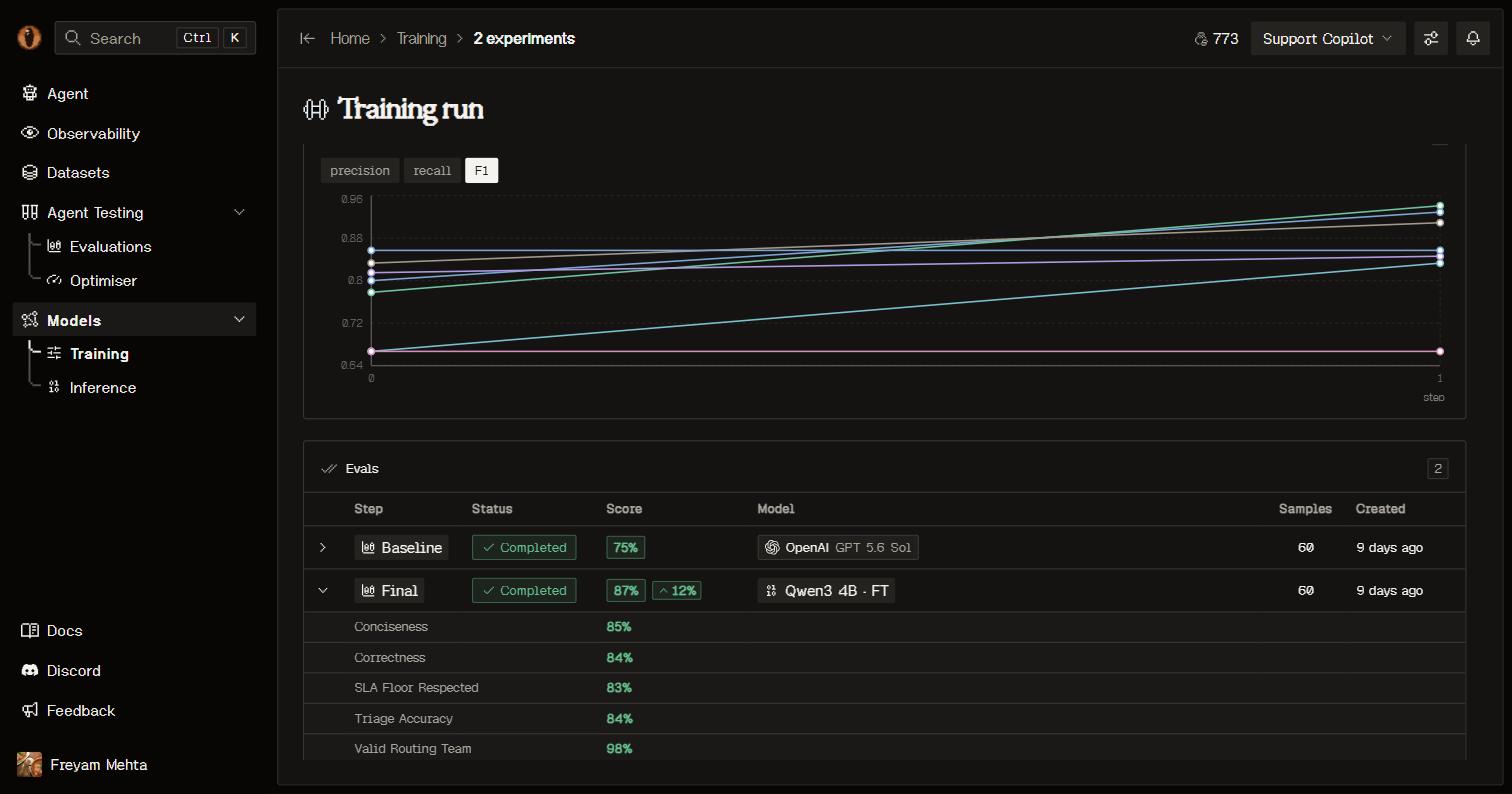
<Frame caption="Baseline and Final rows per experiment, scored with the same graders.">
  <img src="https://mintcdn.com/overmind-b84ae13c/OG-4bZDDAnV78HJp/images/platform/training-evals.jpg?fit=max&auto=format&n=OG-4bZDDAnV78HJp&q=85&s=b91fe8ecb6b06e7c89d0901a2198b8e9" alt="Training evals table with baseline and final scores" width="1512" height="794" data-path="images/platform/training-evals.jpg" />
</Frame>

When your expected outputs are labels, you also get per-class precision, recall and F1, accuracy, and a confusion matrix — so a classifier tells you which class it's getting wrong, not just that it improved.
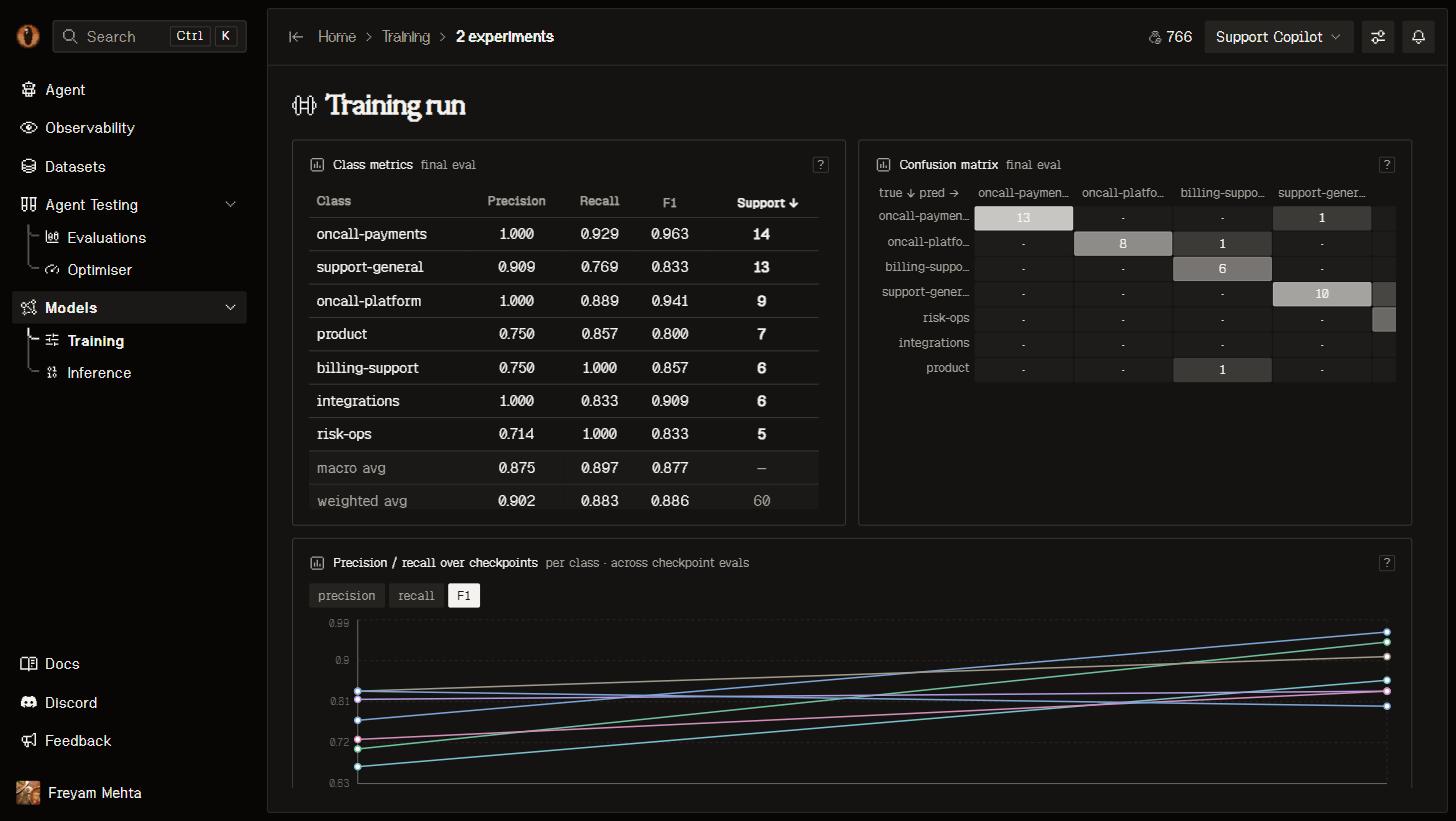
<Frame caption="Classification metrics for a routing capability: per-class F1 and the confusion matrix.">
  <img src="https://mintcdn.com/overmind-b84ae13c/OG-4bZDDAnV78HJp/images/platform/training-class-metrics.jpg?fit=max&auto=format&n=OG-4bZDDAnV78HJp&q=85&s=fbe16298a544fc62c521287af1724545" alt="Per-class metrics and confusion matrix on the training page" width="1456" height="821" data-path="images/platform/training-class-metrics.jpg" />
</Frame>

## Ship it

A finished job deploys its model for you. It appears on [Inference](/models/inference) and in your capability's **Models** tab with a reference like `ft-9635f347-qwen3-4b`, and its weights are downloadable from the model page or with `overmind model download-checkpoint`.

Two ways to put it in front of traffic:

* **Make live** points your capability's alias `overmind/<capability-uuid>` at the new model. Your next request hits it, with no code change at all.
* **Copy** gives you a prompt for your coding agent that retargets your LLM client at the model directly. The edit lands in your repository through your normal review.

## Good to know

* Quality comes from the data, not the hyperparameters. Get the version fitting the train contract first.
* A run freezes the version it trained on, so its numbers stay true while you keep curating for the next one.
* Every experiment reports what it cost when it finishes, and you see the estimate before you launch.
* A model serving real traffic is producing traces again — which is the data for your next round.

## Next steps

<CardGroup cols={2}>
  <Card title="Call your model" href="/models/inference">
    The OpenAI-compatible endpoint, the capability alias, and how serving behaves.
  </Card>

  <Card title="Improve your data" href="/core/datasets">
    Better rows beat better hyperparameters. Curate and train again.
  </Card>

  <Card title="Compare models first" href="/agent-testing/optimisers">
    Backtest several models over your dataset before you train one.
  </Card>

  <Card title="Sharpen your graders" href="/agent-testing/eval">
    The benchmark is only as honest as the judges behind it.
  </Card>
</CardGroup>